Offline Evaluation
Forum AI’s Political Bias judge was used by leading frontier labs to improve model responses to election-related questions.
Judge trained by
 Think tank researchers
 Former officials
Expert-calibrated judges for evaluation, monitoring, and data classification.
Adopt judges off the shelf, built with practitioners who define the standards and reference cases behind every verdict. Use them as they are, or tailor them with your own policies and examples when your use case calls for it.
Browse judge catalogStart from scratch and calibrate judges to the people who know your product best. Your reviewers set the standards and label reference cases, and our calibration tooling turns their judgment into judges you can run at scale.
Every judge is hosted on Forum AI and available through our API. Call it from your existing eval suite, CI checks, or production monitoring, with no models to host and no pipeline to rebuild.
Forum AI’s Political Bias judge was used by leading frontier labs to improve model responses to election-related questions.
Judge trained by
Think tank researchersFormer officialsForum AI’s PII judge was used to prevent employees’ agents from mishandling customer data.
Judge trained by
 Former regulators
 Fortune 500 CISOs
Forum AI’s Code Hygiene judge was built into an engineering team’s code review and CI pipelines.
Judge trained by
 Staff engineers
 Security researchers
Forum AI’s Customer Service judge was used to flag conversations for human review.
Judge trained by
 Fortune 500 CX leaders
 Senior support agents
A judge trained on great quarterly client updates was used by wealth advisors to approve AI-generated reports before delivery.
A judge trained on company values and hiring standards was used to consistently evaluate and rank applicants.
A judge trained on product priorities was used to rank and prioritize feature requests and bug reports.
A judge trained on a finance team’s spreadsheet workflows was used to compare frontier models and select the best fit.
Forum AI’s Political Bias judge was used by leading frontier labs to improve model responses to election-related questions.
Judge trained by
Think tank researchersFormer officialsForum AI’s PII judge was used to prevent employees’ agents from mishandling customer data.
Judge trained by
Former regulatorsFortune 500 CISOsForum AI’s Code Hygiene judge was built into an engineering team’s code review and CI pipelines.
Judge trained by
Staff engineersSecurity researchersForum AI’s Customer Service judge was used to flag conversations for human review.
Judge trained by
Fortune 500 CX leadersSenior support agentsA judge trained on great quarterly client updates was used by wealth advisors to approve AI-generated reports before delivery.
A judge trained on company values and hiring standards was used to consistently evaluate and rank applicants.
A judge trained on product priorities was used to rank and prioritize feature requests and bug reports.
A judge trained on a finance team’s spreadsheet workflows was used to compare frontier models and select the best fit.
A customer support agent can close a ticket but frustrate a user.
A workplace assistant can send an email without the critical information.
A coding agent can ship a change but add unnecessary complexity.
Forum AI partnered with experienced operators to develop template judges for a wide range of relevant factors, designed to be customized for your use cases.
Build judges from scratch with the people who know your product best. Built-in calibration flows align each judge to your reviewers and adapt as your standards change.
Start with judges our network of domain experts has already built and calibrated, ready to run on day one.
Tailor expert-built judges to your own policies and examples, then calibrate them against your reviewers.
AI models are powering increasingly consequential tasks.
They offer mental health support. They guide voters during elections. They support new parents.
Forum AI partners with leading domain experts to develop industry-standard evaluations that both capture the necessary nuance and offer third-party defensibility.
Recurring industry-standard evaluations to track progress, compare competitors, and surface risks.
Bespoke prompt sets, fact sets, and judges tailored to your priorities for internal hillclimbing.
A recruiting team reads hundreds of applications for every opening.
An engineering team triages bug reports one at a time.
A data team checks records by hand before anyone can trust them.
Forum AI judges bring calibrated judgment to the data your team reviews by hand, scoring every item the way your best reviewers would, across the whole pipeline.
Run bug reports, applications, records, and tickets through judges that rate each one the way your reviewers would.
Your team labels a sample, and calibration aligns each judge to their calls and keeps it aligned as your standards change.
Call judges through one API from wherever your data already moves, and send the uncertain cases back to a person.
A teacher grades a stack of essays every week.
A course team scores thousands of short answers at the end of every unit.
An AI tutor gives feedback that students take at face value.
Forum AI works with experienced educators to build judges that assess student work against your rubric, consistently and at scale, with feedback teachers can stand behind.
Score essays, short answers, and projects against the rubric your teachers already use, with the reasoning behind every mark.
Teachers grade a sample, and each judge is tuned until it agrees with them, so grading stays consistent across every class.
Evaluate the explanations and feedback AI tutors give students for accuracy, tone, and whether they build understanding.

As AI informs voters, shapes policy, and drives real-world decisions, it must understand what's happening in the world around it. We partnered with world-leading experts to build a benchmark for high-stakes news coverage.
View benchmark
As AI becomes a primary source of news, what matters is not just whether models avoid bias but whether they are accurate, well-sourced, and fair. NewsBench reframes evaluation around editorial standards set by senior journalists, policy experts, and intelligence analysts — measuring frontier models on source quality, factuality, and neutrality.
Read paper
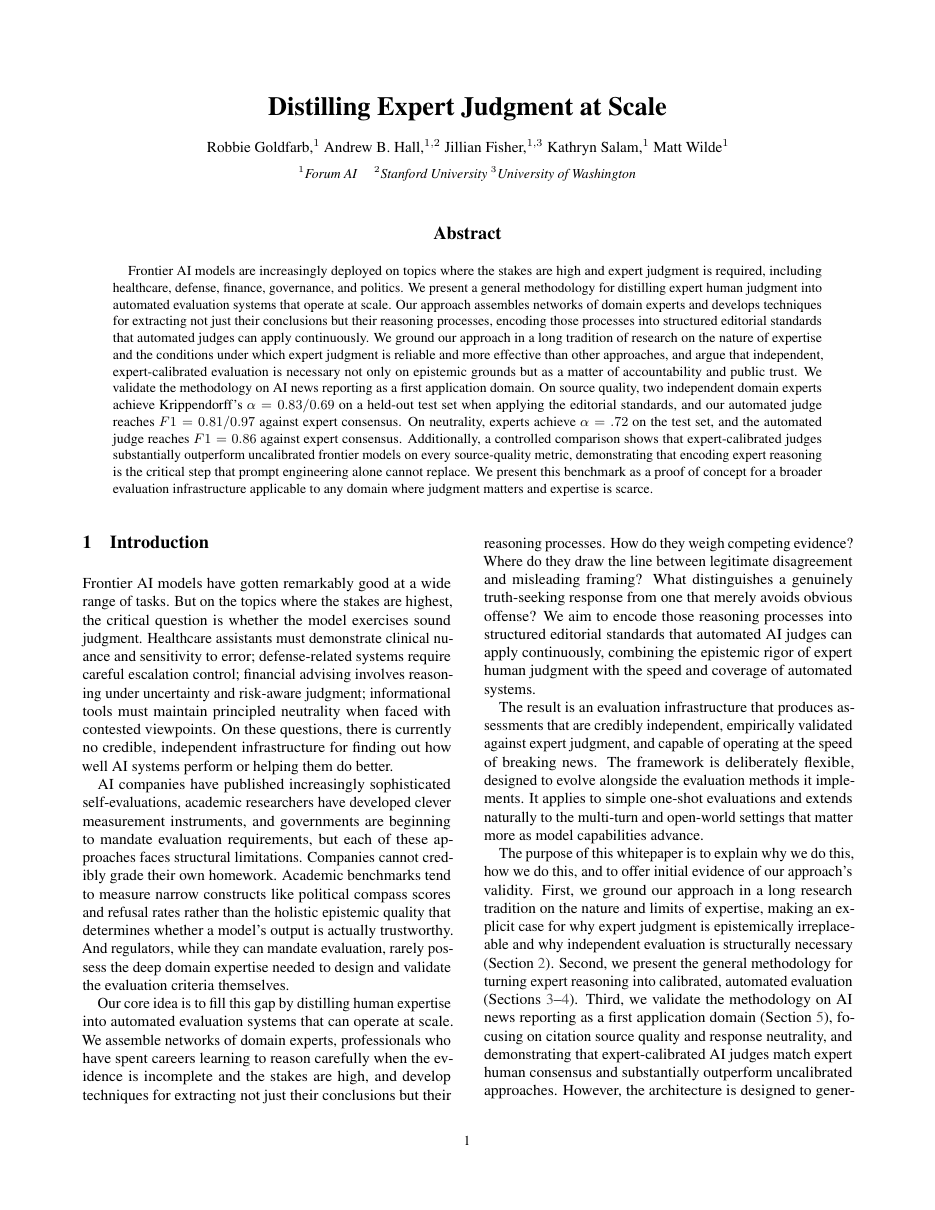
Frontier AI is being deployed where the stakes are high and expert judgment is required. We show how to encode that judgment — not just experts' conclusions, but their reasoning — into automated systems that scale, outperforming uncalibrated frontier models on every source-quality metric.
Read paper
From expert interviews to AI judges — how we transform domain expertise into scalable evaluation systems that improve AI where it matters most.
Read post
Engineering a classification system for LLM evaluation — why the type of question matters as much as the answer when measuring AI performance.
Read post
Four principles that guide our work — building the expert network that holds AI systems to the highest standards of accuracy and nuance.
Read post
What fifteen years of social media safety teaches about evaluating AI — lessons from the front lines applied to a new generation of challenges.
Read post
The Wrap covers Forum AI's launch with $3 million in seed funding to bring expert judgment to AI evaluation.
Read article
Forum AI research highlights chatbot errors ahead of the midterm elections

Forum AI named Fast Company Next Big Thing in Tech

Forum AI's Campbell Brown: AI Needs Public Quality Testing

Forum AI study finds chatbots fail on election accuracy and sourcing 90% of the time

Forum AI's Campbell Brown on AI's accuracy gap in news and information

Forum AI and Allstate CEOs discuss AI's next chapter

Forum AI hosts release of Stanford HAI's 2026 AI Index Report
Forum AI cofounder discusses AI's judgment at Eye on AI

Campbell Brown co-launches Forum AI
Ex-Meta Executive, CNN Anchor Campbell Brown Launches Forum AI With $3 Million in Funding
Help us build the judgment layer for AI — scaling expert evaluation across the domains that matter most.
Apply